

For teams considering a Data Ladder alternative, the challenge often extends beyond finding duplicate records. In our customer conversations, we hear from organisations trying to recognise and reconcile the same record across separate business systems, even when their details differ – while trying to preserve the original records, and understanding how each matching decision was reached. As new data arrives, they need those connections to hold up without repeatedly rebuilding the process.
We’ve written this guide to connect those practical requirements with what the available platforms offer. Drawing on the questions our team works through with customers and prospects, we explore where WinPure Clean&Match and other Data Ladder alternatives fit, what distinguishes their approaches and what deserves closer examination before you invest.
Note: As a software provider, we bring our own perspective, and we strive to make this comparison fair and objective. We encourage you to use free trials where available and test the tools against a representative sample of your own data. Where a trial is unavailable, speak with the provider’s representatives and request a demonstration around your requirements, so you can assess how the platform would handle the work you need it to do.
Data Ladder Alternatives Compared
The alternatives below serve different kinds of data projects, from resolving customer records across disconnected systems to managing master data across an organisation. We’ll look at what each platform enables your team to do, how it fits into an ongoing workflow and where its scope may differ from what you need.
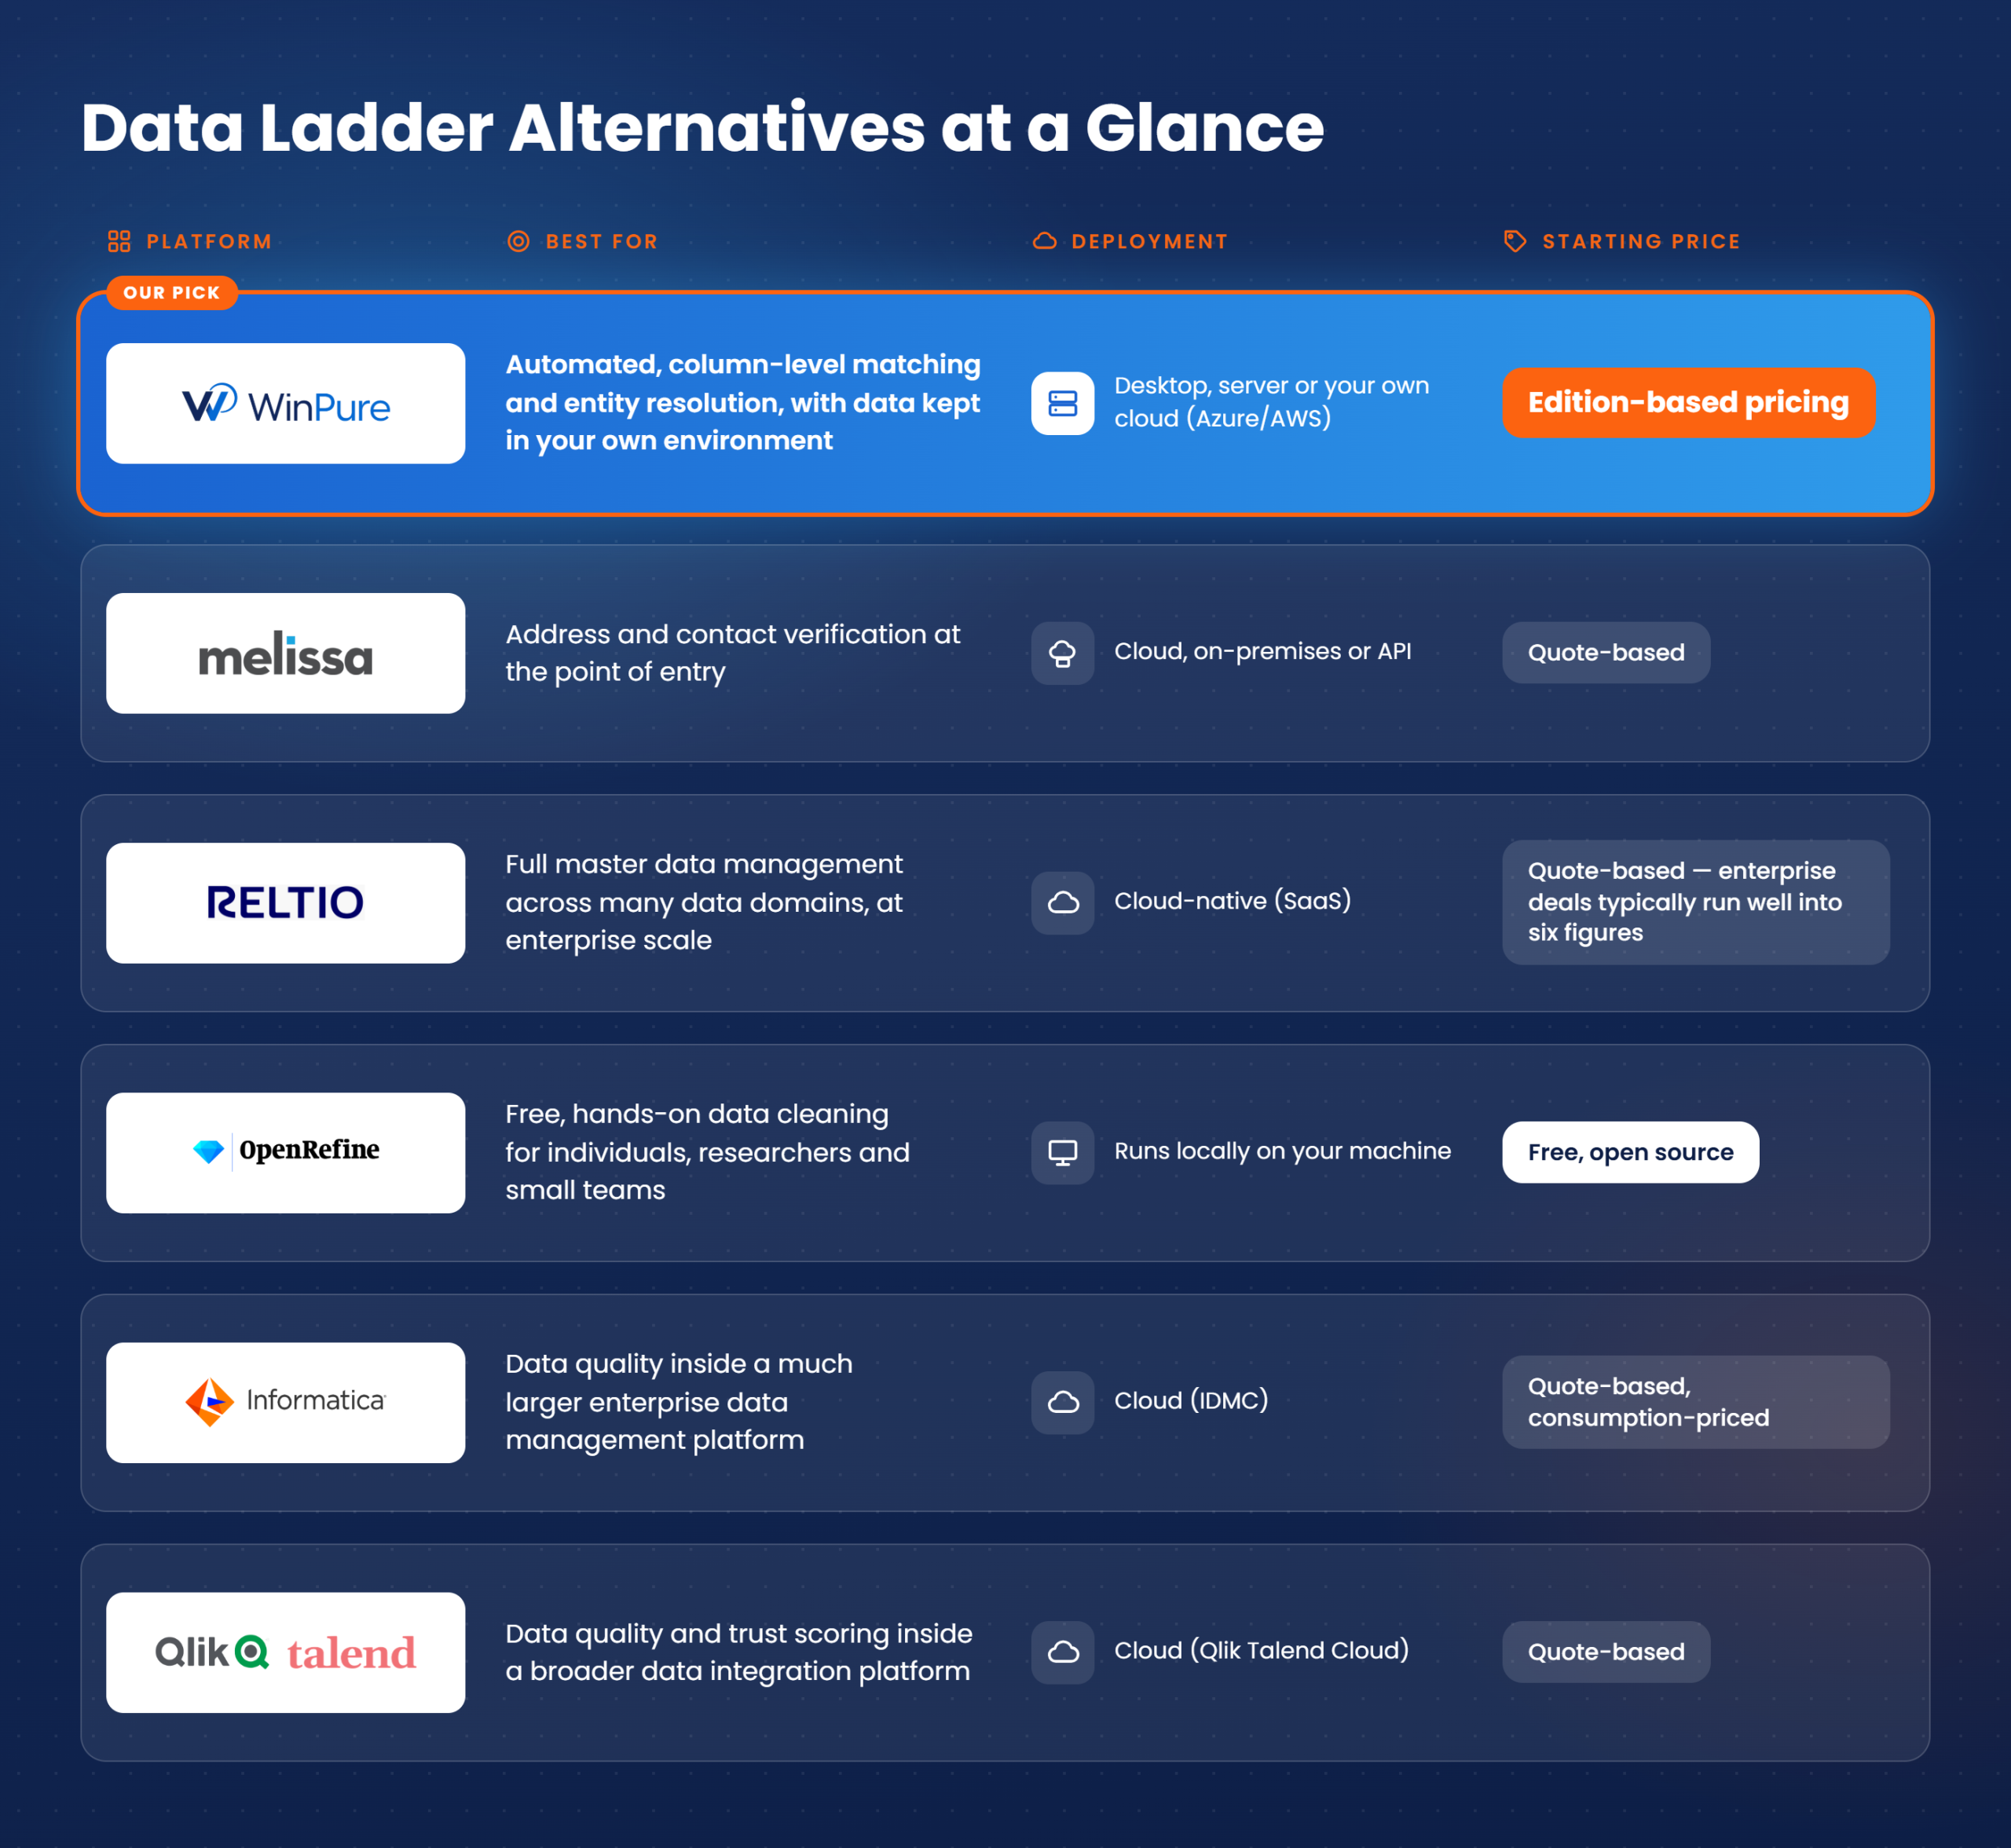
1. WinPure Clean&Match Enterprise: Best Overall Data Ladder Alternative
WinPure Clean&Match and Data Ladder both bring core data quality processes, including profiling, cleansing, matching and golden record creation, into one platform. WinPure’s distinction lies in how it combines traditional configuration with built in intelligence, giving teams different ways to tackle their data within a connected workflow. Users can define detailed cleansing and matching rules, build reusable Regex libraries and retain granular control, while drawing on intelligent recommendations where the data calls for a different approach.
Definition
What Is WinPure Clean & Match Enterprise?
WinPure Clean & Match Enterprise is a no-code data quality platform from WinPure, a global data quality software provider established in 2002. It supports organisations working to improve the quality and reliability of business data. Version 12 brings together a re-engineered matching engine, a redesigned matching interface, MatchGraph™, Golden Record Identity™, a dedicated Audit & Compliance module and connectivity through REST API, MCP and AIConnect™. Core data quality processing runs locally. Optional external verification and AI services may involve transmitting selected data to third-party providers, depending on configuration.
With features like adaptive matching users get recommended match algorithms and settings auto mapped to the fields they want to match. Meanwhile for more complex entity resolution, WinPure is enabled with a match engine powered by Senzing, a renowned entity resolution provider to assess identity evidence across fragmented records. For teams comparing the two platforms, this combination of control and automation is a key reason to consider WinPure: it allows analysts to apply their own logic alongside specialised intelligence, helping them resolve difficult cases without having to anticipate every variation in a manually constructed rule.
WinPure Key Features & How it Differs from Data Ladder
The differences become clearer when you look at how each platform approaches matching decisions, maintains resolved identities and supports the work around them.
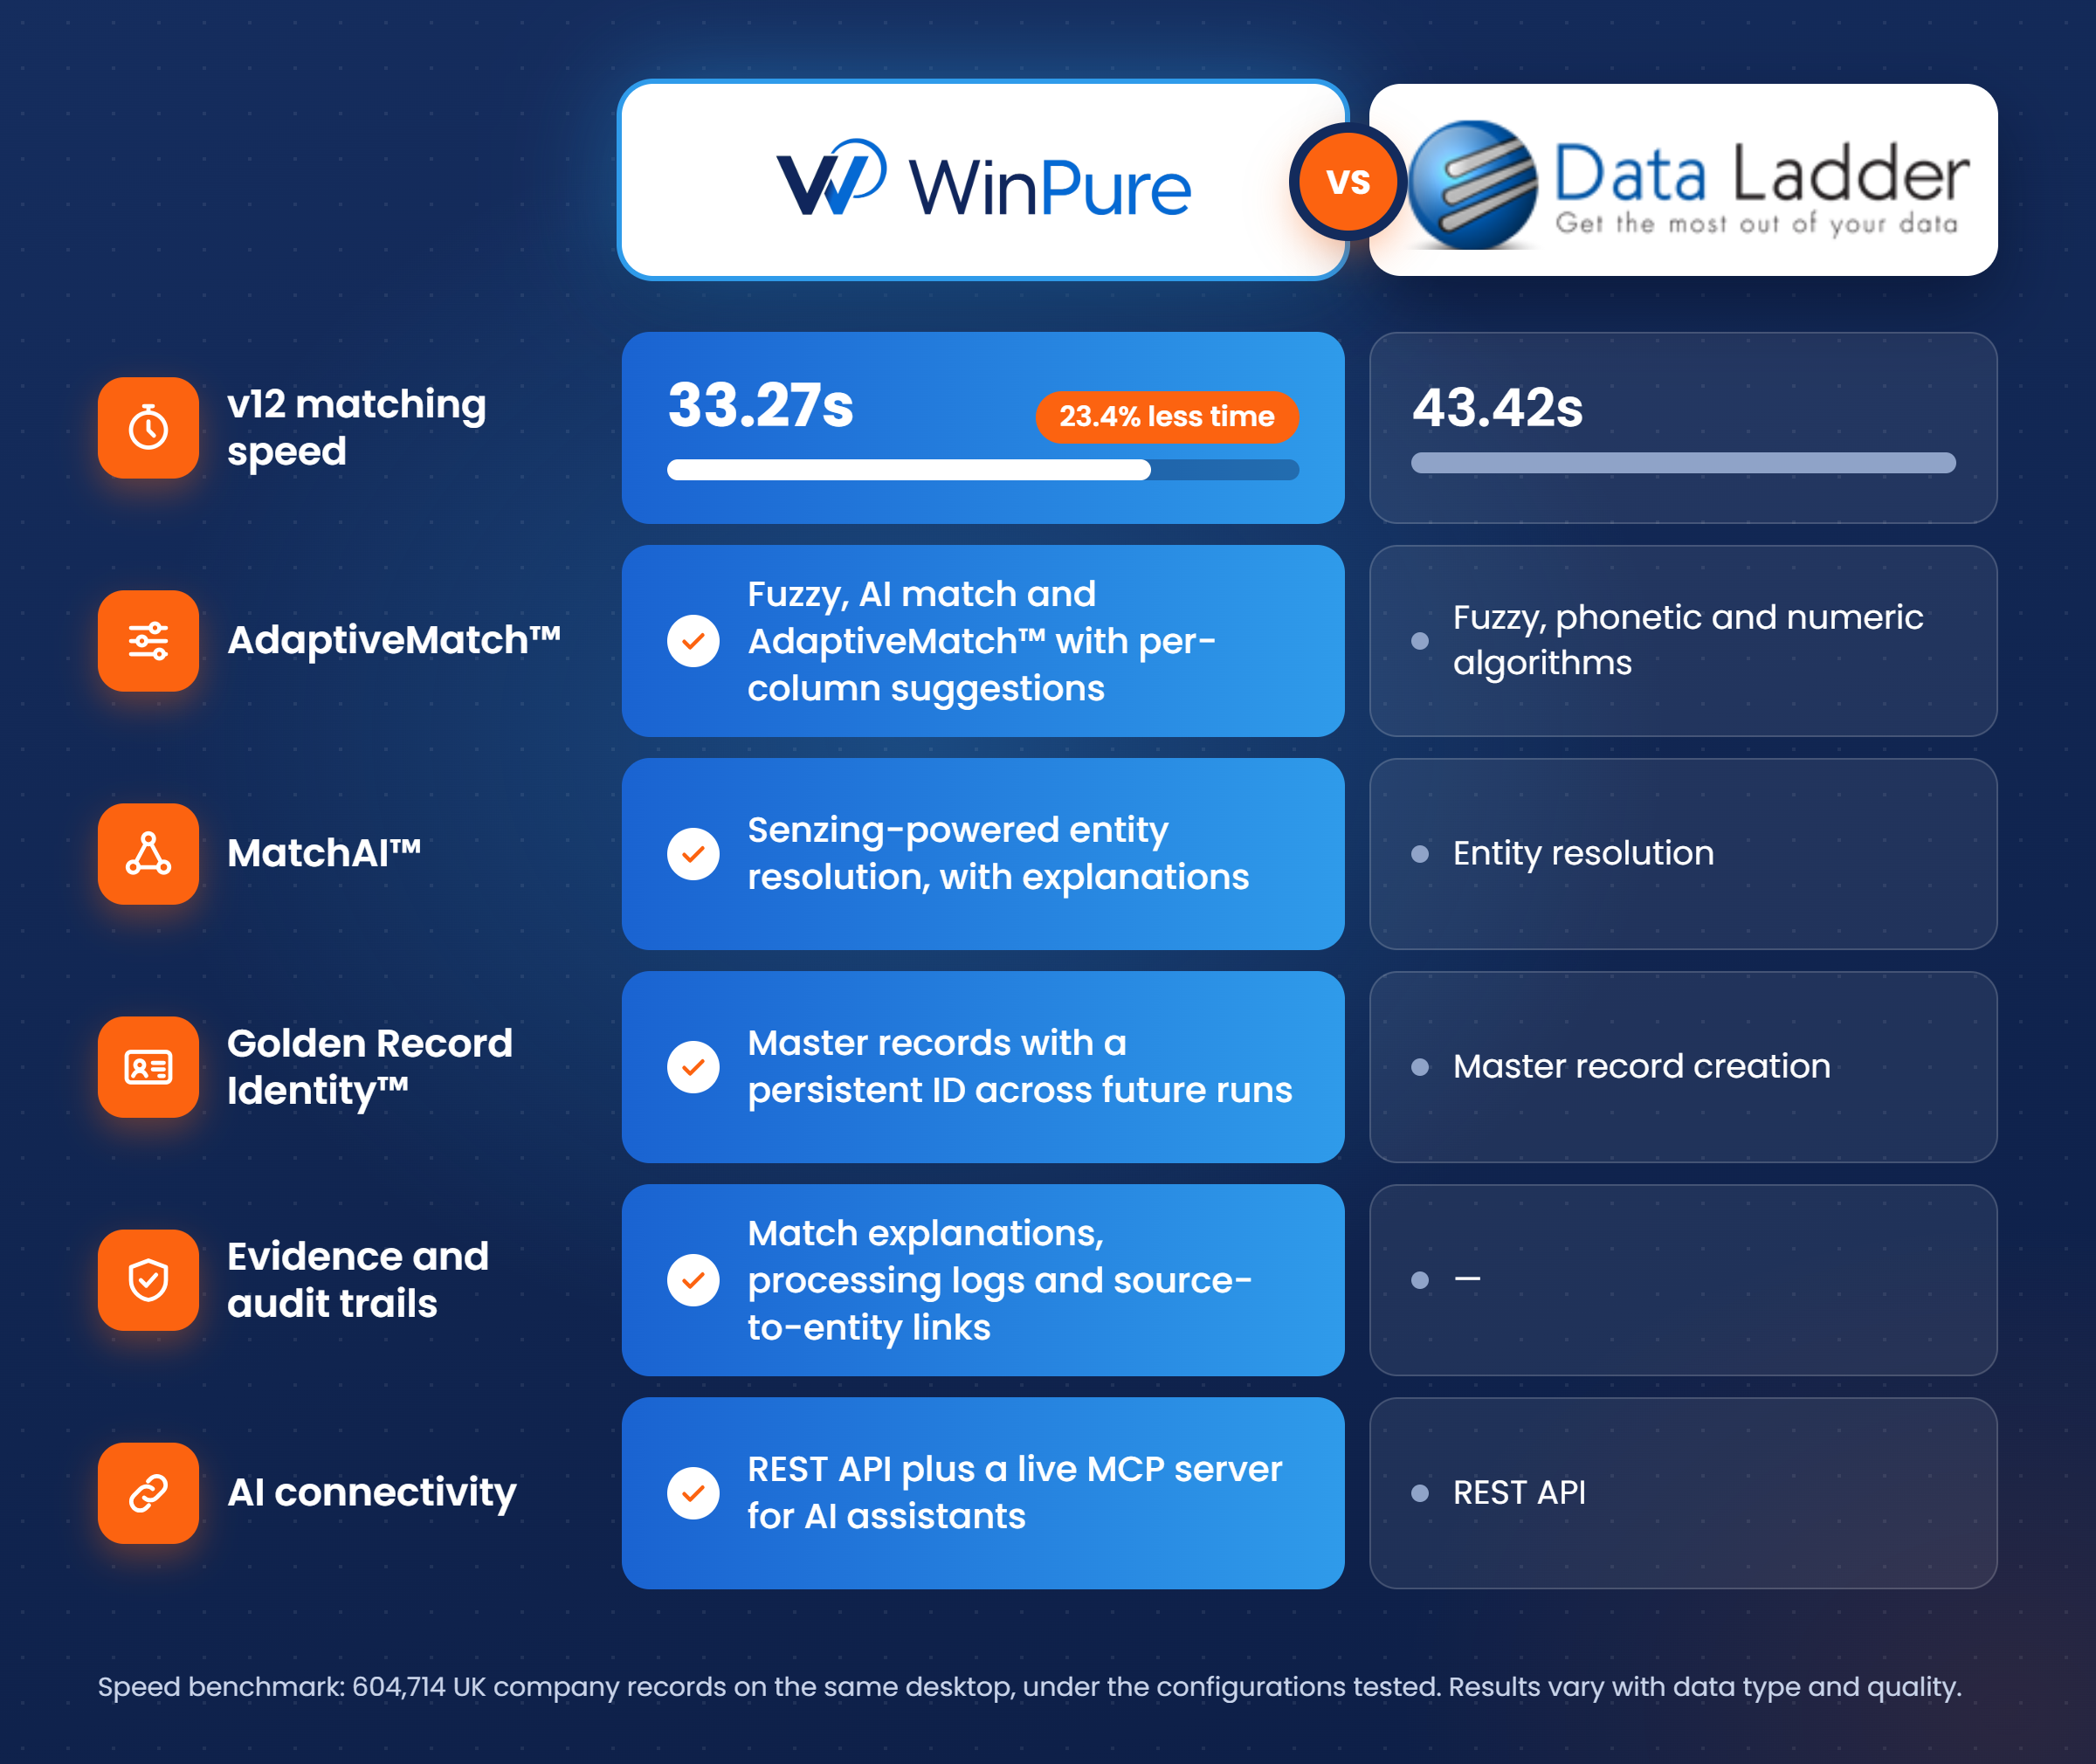
🔷AdaptiveMatch™ combines recommendations with detailed configuration. Data Ladder provides proprietary fuzzy, phonetic, numeric and other matching algorithms. WinPure has all the same match capabilities but with an additional match library that identifies data types and suggests appropriate algorithms and settings for individual columns. Analysts can combine traditional fuzzy match, AI match, and AdaptiveMatch™ to solve their most complex duplication and consolidation challenges. The outcome is entity and identity resolution that teams can move back into their integrated platforms, each with an optional golden identity that helps retain the consolidated data in future runs.
🔷MatchAI™ brings Senzing powered entity resolution into the same workflow. Data Ladder also supports entity resolution, so the distinction is how records are assessed. Alongside WinPure’s configurable matching, MatchAI™ uses Senzing’s engine to evaluate the whole dataset to identify who is who and who is connected to whom. This gives teams another approach when names, addresses and identifiers vary across sources, with explanations to support investigation of the resulting groups. Customers can use traditional matching for clearly defined comparisons and entity resolution for more fragmented identities within the same platform.
🔷Golden Record Identity™ supports continuity as new data arrives. Data Ladder supports master record creation, while WinPure’s Golden Record Identity™ also gives each resolved entity a persistent identifier that carries its identity into subsequent processing. As new records arrive, teams can match them against established entities and retain the same ID, even when names, addresses or other details have changed. This helps prevent the same customer or supplier from being treated as a new entity each time data is imported, keeping reporting and phased migrations aligned. By preserving the links to underlying source records, persistent IDs also give teams a traceable connection between the original information and its master record.
🔷Matching evidence and audit trails support governance throughout the process. WinPure combines explanations of match decisions with processing logs and links between source records and resolved entities, giving teams the ability to investigate why records were grouped as a match. This level of transparency and traceability has helped WinPure customers with critical data governance and compliance requirements where it is imperative for teams to understand why certain decisions about the records were made.
🔷The v12 matching engine makes performance a concrete evaluation point. In our benchmark using 604,714 UK company records on the same desktop, WinPure v12 completed matching in 33.27 seconds, compared with 43.42 seconds for Data Ladder, taking 23.4% less time under the configurations tested. Faster processing can give analysts more room to refine rules and check results during a project. However, a key point to note here is that separate vendor benchmarks cannot establish which will be faster on your workload and any claims of speed or accuracy is highly subjective to the type and quality of data.
🔷Native MCP connectivity extends integration to compatible AI assistants. Both platforms offer REST APIs for application integration. WinPure v12 additionally provides a live MCP server, enabling compatible AI assistants and agents to access supported WinPure capabilities through configured tools and permissions. For teams incorporating AI assistants into their operations, this provides an additional integration route alongside conventional APIs and automated workflows.
WinPure Pricing
A free 30-day, full access trial is available for users who want to test on their sample data. Once satisfied, they can choose from a range of paid editions — Small Business, Pro Business, Enterprise and Enterprise with Address Verification — each built for solving specific data consolidation needs.
Which Should You Choose?
Choose Data Ladder if…
- You need a server-hosted web application deployed through Docker.
- Your current DataMatch workflows meet your needs and switching costs would outweigh the gains.
Choose WinPure if…
- You want the most appropriate matching algorithm automatically selected for each column, with the flexibility to customise algorithms, field weights and thresholds.
- You need Senzing-powered entity resolution for fragmented or incomplete records.
- You need persistent entity identifiers that survive subsequent matching runs as source records change.
- You need advanced international address parsing and multilingual normalisation to accurately structure and standardise address data from over 100 countries.
- You need address verification across international datasets, with Loqate coverage spanning 250 countries and territories.
- You want AI assistants to work with your data quality processes through MCP.
- Business users need to configure matching without code.
Our verdict: Data Ladder remains a capable platform, and its new web release suits container-first teams. For organisations that want finer matching control, persistent Golden Record Identity™, AI-powered entity resolution, international address parsing, global address verification, dedicated change auditing and AI connectivity in one no-code tool, WinPure Clean & Match Enterprise v12 is a compelling Data Ladder alternative. The best way to decide is to run your own data through both tools.
2. Melissa: Best for Contact Data Verification and Enrichment
Melissa is a strong Data Ladder alternative for organisations whose data quality challenges centre on the customers they need to contact, serve or deliver to. Its appeal lies in combining matching and cleansing with reference data services that help establish whether contact details are valid and fill gaps in existing records. For teams dealing with failed deliveries, outdated addresses or incomplete customer information, that verification capability can directly support the operational work behind a data quality project.
Melissa Key Features
- Broader contact verification: While Data Ladder offers address verification, Melissa’s portfolio also covers email, phone and name verification, making it relevant for teams improving contactability across several channels.
- International address coverage: Melissa documents verification across more than 250 countries and territories, with address parsing, standardisation and geocoding. Check the level of verification available in the countries you serve.
- Configurable matching and consolidation: MatchUp supports customised matching criteria, while Unison combines fuzzy matching, golden record survivorship, profiling and scheduled cleansing. These capabilities overlap with Data Ladder, so representative data testing will help establish suitability.
- Enrichment and existing integrations: Melissa offers services to supplement customer records and integrations for platforms including Salesforce, Microsoft Dynamics, SSIS and Azure Data Factory. Availability and licensing vary by product.
Melissa Pricing
Selected verification services offer credit purchases or subscriptions. For a complete matching and data quality deployment, request pricing for the products and volumes required. Melissa advertises a free 30 day trial through its demo enquiry page; confirm which products it covers.
Which Should You Choose?
- Choose Data Ladder if your priority is an integrated profiling, cleansing, matching and merge workflow with REST API access.
- Choose Melissa if contact verification, international address quality and customer enrichment are central to your requirements.
Our verdict: Melissa’s strongest appeal is the breadth of its contact verification and enrichment services. Establish which products your project requires before comparing its overall cost and workflow with Data Ladder.
3. OpenRefine: Best Free Alternative for Data Cleanup
OpenRefine suits teams that need to investigate messy datasets, standardise inconsistent values and prepare information for further processing without a software licence cost. Its strength is interactive cleanup, giving analysts tools to explore patterns and review changes as they work.
OpenRefine Key Features & How It Differs from Data Ladder
- Faceting and transformations support detailed cleanup. Analysts can isolate inconsistent values, split or combine columns and apply transformations across selected records. This makes OpenRefine useful for investigating unfamiliar datasets and correcting recurring formatting problems.
- Clustering helps standardise similar text values. OpenRefine groups possible variations of the same value for users to review and merge. Its documentation distinguishes this syntactic clustering from semantic entity resolution, an important consideration when comparing it with Data Ladder’s configurable record matching.
- Reconciliation connects records to reference sources. Compatible services allow teams to match values against sources such as Wikidata or a locally supplied dataset. Results can include entity identifiers and additional information, with human review needed for uncertain candidates.
- Operation history supports repeatable transformations. Changes can be undone, and supported operations can be exported and applied to another dataset. Some automation is possible, although interactive tasks such as clustering still require supervision. Data Ladder provides scheduling and API workflows for recurring processing.
- Core processing runs on your own computer. OpenRefine uses a browser interface to access a local application. Connecting to external reconciliation services or fetching web data can transmit selected information outside that environment.
OpenRefine Pricing
OpenRefine is free and open source, with no licence fee or trial expiry. Allow for the time needed to learn transformations, review clusters and configure any external services.
Which Should You Choose?
- Choose Data Ladder if you need configurable record matching, merge and survivorship rules, and recurring processing through scheduling or APIs.
- Choose OpenRefine if your priority is hands on dataset exploration, text standardisation and reviewed cleanup without a software licence cost.
Our verdict: OpenRefine is a practical choice for focused cleanup projects where an analyst can investigate and approve changes. For teams replacing an established Data Ladder workflow, test how much of the matching, consolidation and recurring processing your project requires before treating it as a complete replacement.
4. Reltio: Best for Enterprise Master Data Management
Reltio suits organisations that need to maintain shared master data across business systems, with ongoing responsibility for its quality, relationships and governance. Its scope includes customer, supplier, product and location data, making it relevant when evaluating a Data Ladder alternative forms part of a wider master data management programme.
Reltio Key Features & How It Differs from Data Ladder
- Multidomain MDM: Maintains customer, supplier, product and location data within a shared master data platform.
- Continuous matching: Checks new and updated records against existing profiles to keep master data current.
- Dynamic survivorship: Applies rules to select preferred values while preserving contributing source information.
- Persistent identities: Maintains entity IDs and relationships across connected business systems.
- Cloud delivery: Provides a hosted SaaS platform for ongoing master data management.
Reltio Pricing
Request a proposal covering your required products, data volumes and implementation scope. Reltio advertises 30 days of free access on its MDM page; confirm the capabilities and support included before planning an evaluation.
Which Should You Choose?
- Choose Data Ladder if your primary requirement is cleansing, matching and consolidating datasets without establishing a broader MDM platform.
- Choose Reltio if you need continuously maintained master profiles, source traceability and relationship management across multiple business systems and data domains.
Our verdict: Reltio deserves consideration when your organisation is investing in master data as an ongoing operational capability. For a focused cleansing or deduplication project, its wider scope may introduce more implementation work than the requirement justifies.
5. Qlik/Talend: Best for Data Quality Within Integration Pipelines
Qlik Talend brings data integration, quality and governance into a broader platform. Its profiling, cleansing and matching capabilities overlap with Data Ladder, but the wider offering suits teams that also need to move and transform data between systems. The relevant comparison is therefore the data quality workflow and the edition that supports it.
Key Features
- Profiling and cleansing: Identifies quality issues and applies corrections within data processing jobs.
- Matching and deduplication: Supports configurable matching to identify and consolidate duplicate records.
- Integration pipelines: Embeds data quality tasks into workflows that move and transform data across systems.
Qlik Talend Pricing
Qlik Talend Cloud offers several subscription tiers with capacity based pricing. Confirm which edition includes the profiling, matching and governance capabilities you need, alongside the usage measures that determine cost.
When Does It Make Sense?
Qlik Talend deserves consideration when data quality needs to operate within an integration programme, particularly if your team already uses its tools and maintains the relevant pipelines. For a focused matching project, compare the configuration and maintenance involved with a dedicated platform.
Our verdict: A relevant option for teams combining data quality with data engineering. Its broader scope adds value when those integration capabilities are part of the requirement.
6. Informatica: Best for Data Quality Across a Wider Data Management Programme
Informatica offers data quality alongside integration, governance, cataloguing and master data management services. For this comparison, its Data Quality offering is the relevant starting point, with the wider portfolio becoming important when organisations need to coordinate quality processes across multiple systems and teams.
Key Features
- Profiling and quality rules: Identifies inconsistencies and supports reusable validation and cleansing logic.
- Ongoing monitoring: Tracks data quality issues as part of recurring operational processes.
- Connected platform services: Works alongside Informatica’s integration and governance capabilities, depending on the services licensed.
Informatica Pricing
Informatica’s cloud platform uses consumption based pricing through Informatica Processing Units, commonly called IPUs. Request an estimate for your intended services and workloads. A free 30 day Cloud Data Quality trial is available.
When Does It Make Sense?
Informatica merits consideration when data quality forms part of an organisation wide data management programme. Teams already using its platform should assess whether extending their existing setup would meet the requirement, while confirming which capabilities require additional services.
Our verdict: A relevant choice when shared quality rules, monitoring and integration with wider data management services matter to the project. For a contained cleansing or matching requirement, evaluate the specific Data Quality service against a dedicated tool before committing to a broader implementation.
Choose Around the Work Your Data Needs to Support
The alternatives in this guide address different requirements. A focused cleansing and matching project, a contact verification programme and an organisation wide master data initiative each call for a different level of investment and ongoing ownership. The strongest choice will be the platform that fits both the immediate problem and the process your team needs to maintain afterwards.
For teams considering WinPure, the appeal is being able to bring different matching approaches into a connected data quality workflow, with control over configuration and continuity between source records, resolved identities and master records. That combination deserves particular attention when difficult matching cases and recurring consolidation are central to the project.
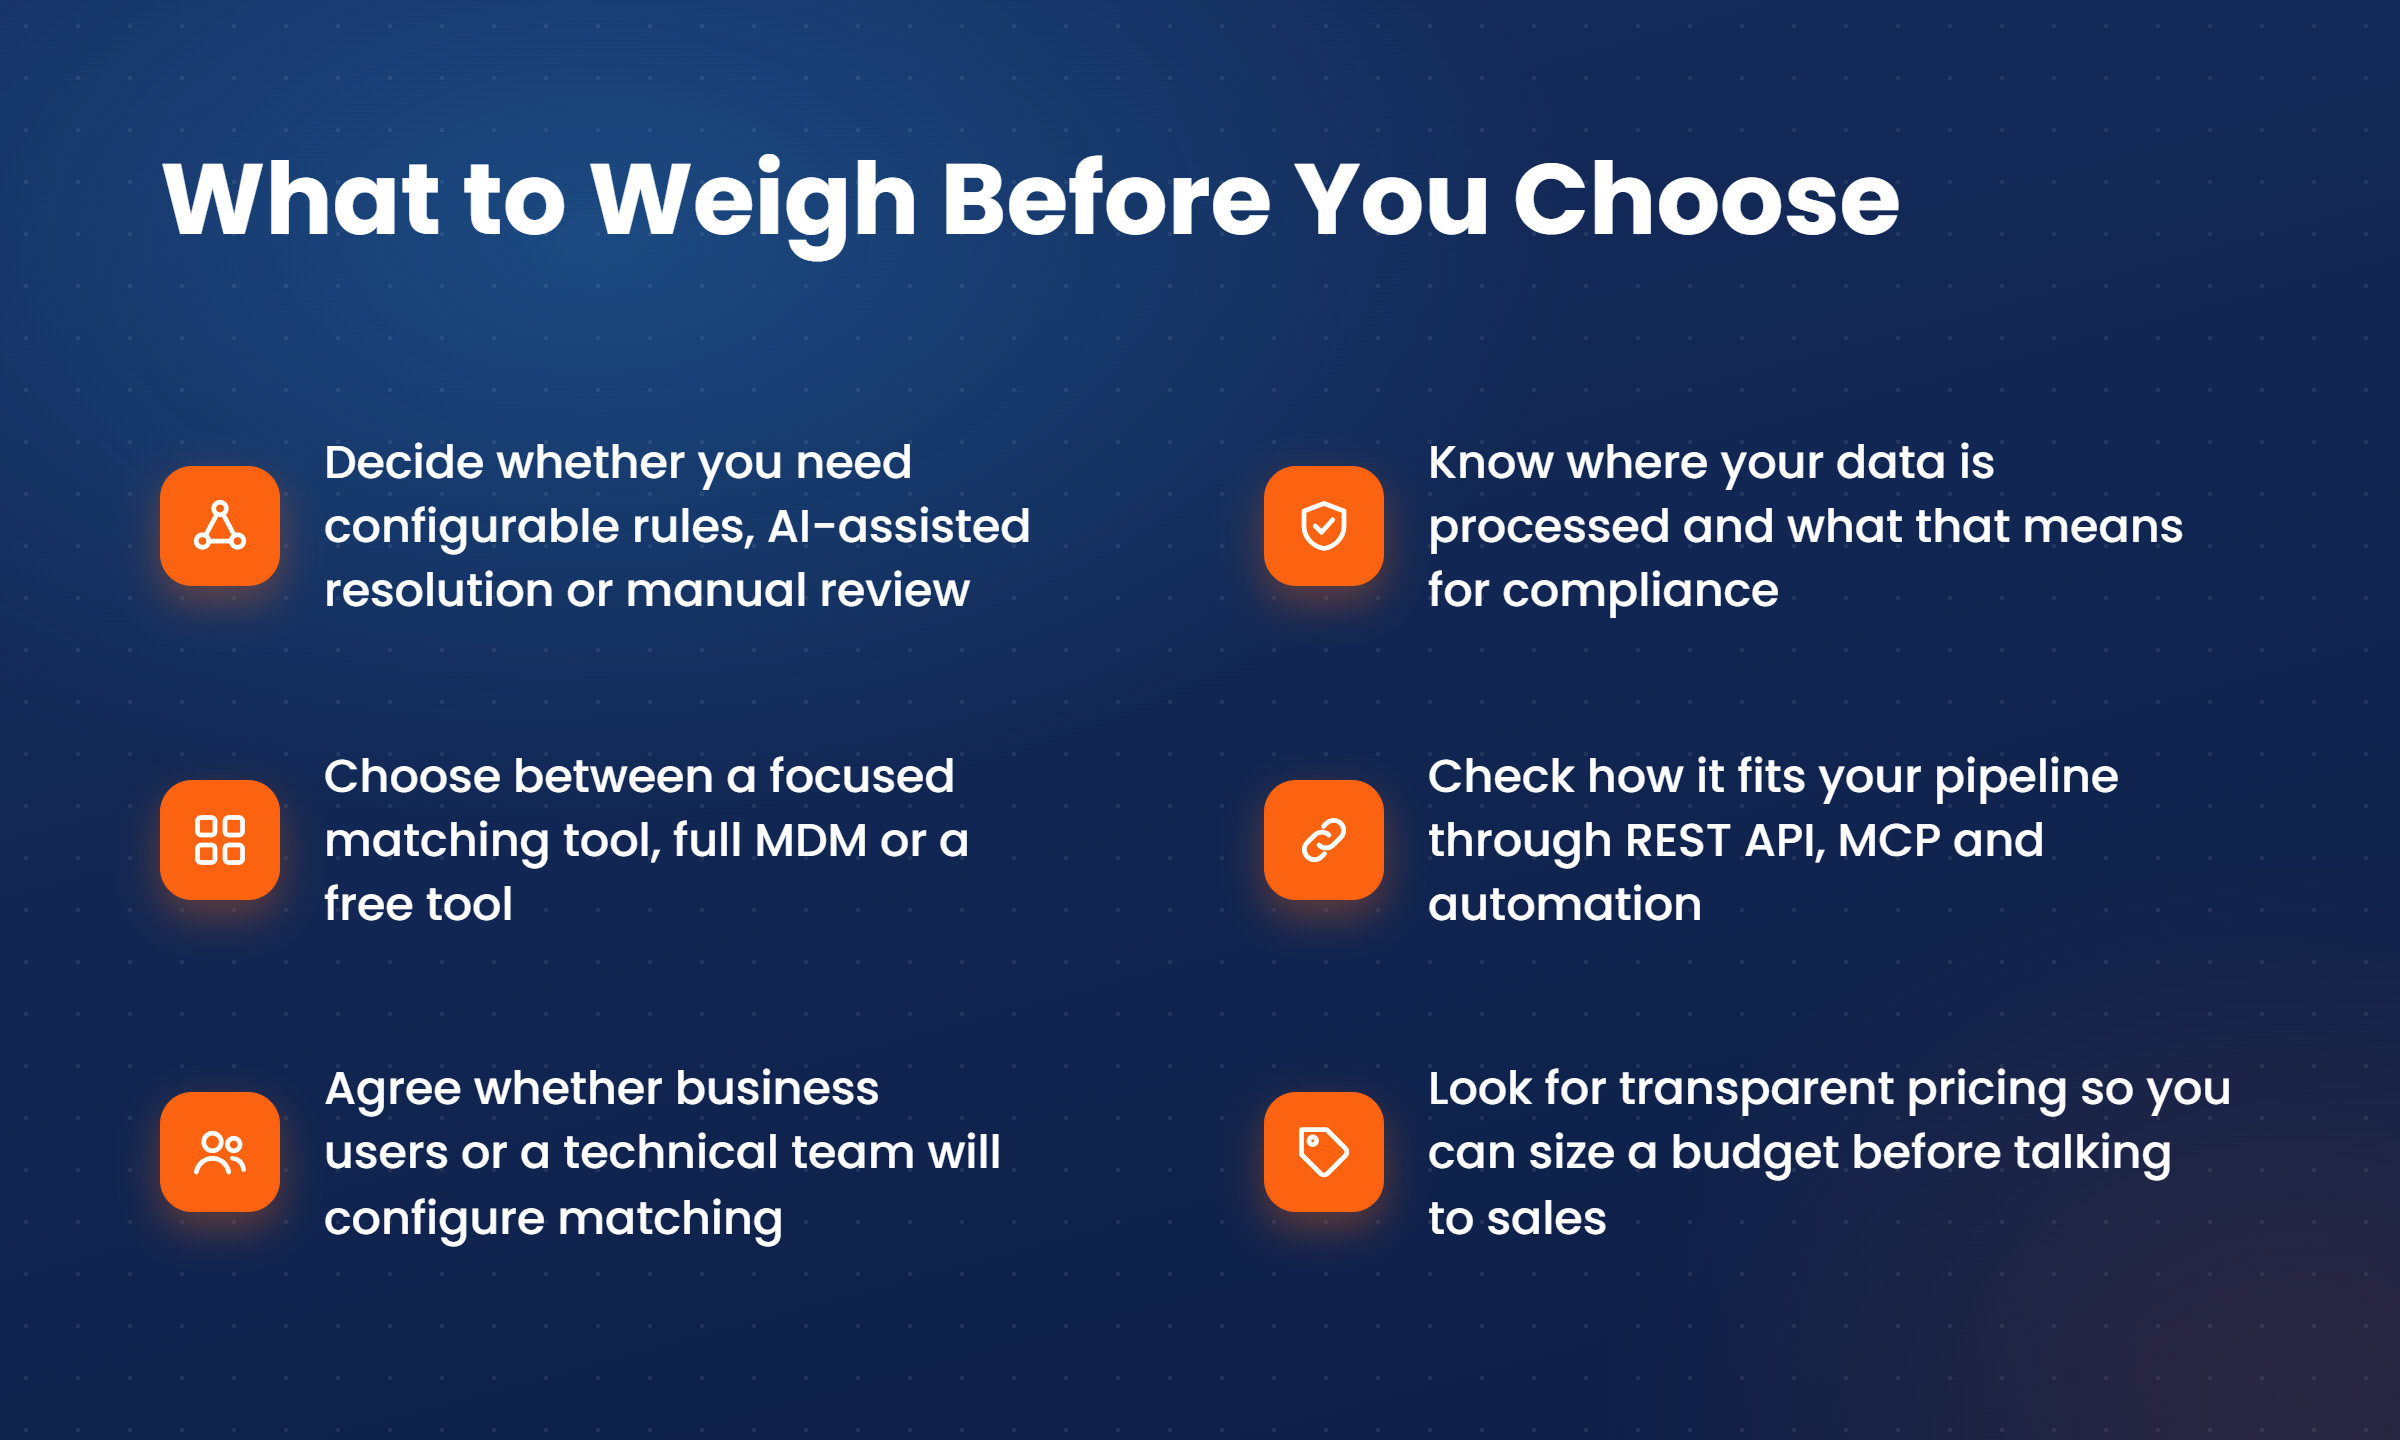
Before committing, put your most challenging records through the platforms you are considering. Review the missed matches and incorrect groupings, investigate how decisions are explained, and introduce another dataset to see what happens as information changes. Alongside processing speed, assess the effort required to reach results your team can trust and repeat.
Put WinPure to the Test with Your Toughest Data
See how WinPure Clean&Match handles your matching challenges, resolves fragmented records and creates traceable master records using your own data.
Frequently Asked Questions
WinPure Clean & Match Enterprise v12 is a direct alternative to DataMatch Enterprise. It covers the same profiling, cleansing, matching and deduplication workflow, and adds column-level algorithm control, Senzing-powered entity resolution, persistent Golden Record Identity™, Libpostal address parsing, Loqate verification, a dedicated Audit & Compliance module and MCP connectivity.
Data Ladder supports golden record creation and describes Golden Record IDs, but an assigned ID does not by itself prove that an entity retains the same identifier across separate matching runs. Equivalent cross-run identity persistence is not available on DataMatch Enterprise. WinPure Golden Record Identity™ is designed to maintain consistent entity IDs as new matching records arrive. Ask both vendors to demonstrate this with repeat-run test data.
A golden record combines the preferred values for a resolved entity. A persistent Golden Record ID identifies the entity consistently over time, even when its preferred values or contributing source records change. WinPure separates identity continuity through Golden Record Identity™ from master record selection and survivorship through SmartMaster AI™.
Export your data, or connect WinPure to the same sources. Then recreate your match definitions as column-level rules in AdaptiveMatch™ and run both tools in parallel on the same dataset to compare results before switching.
Both offer strong fuzzy and phonetic matching. WinPure’s difference is choosing a specific algorithm and weight for each column. Accuracy depends on your data and configuration, so test both on representative records.
Yes. In WinPure’s internal testing, the v12 engine matched about one million records in roughly 15 seconds under specific conditions. Real-world performance depends on hardware, data and matching rules.
WinPure runs locally for core processing, while optional external services may transmit selected data depending on configuration. Data Ladder’s new version is a web application that can be deployed with or without Docker.
No MCP integration is publicly documented for Data Ladder at the time of writing. WinPure v12 includes MCP integration and AIConnect™.
Yes. WinPure uses Libpostal to parse unstructured addresses and normalise international address variations across more than 100 countries and dozens of languages. Separately, Loqate provides address verification across 250 countries and territories. A comparable dedicated international parsing feature has not been established for Data Ladder from the information reviewed.
Yes. Data Ladder’s address verification covers the US and Canada, whereas WinPure integrates Loqate for address verification across 250 countries and territories. Verification depth and any usage charges should be confirmed for the countries you need.
WinPure provides a dedicated Audit & Compliance module that records changes made to data for traceability and governance. Data Ladder describes matching auditability, but an equivalent standalone module is not available on DataMatch Enterprise.
Request current prices from each vendor. Request quotes from both and compare total cost of ownership, including licensing, infrastructure, implementation, support and optional services.
Share this article


